Andy in the Cloud

From BBC Basic to Force.com and beyond…


Leave a comment

AI-Enabled Customer Support with DigitalOcean: Less Plumbing, More Focus

There are an increasing number of things that need our focus when building and managing cloud native applications these days—even more so when adding AI capabilities. Continuing my search for fully managed AI services to fill the gap left by Heroku AI, I’m taking another look at DigitalOcean. This time, I’m exploring how much coding and plumbing it takes to build a customer support agent that understands a company’s support policies and answers customer questions through a web interface aswell as a through the companies internal case management system.

I’ll look beyond established expectations for AI-enabled apps, such as managed semantic search, to explore how document ingestion is handled and how much of the work of building an agent with access to tools is already done for me. There’s code accompanying this post so you can try it yourself, too. The visual below highlights the kinds of things we need to think through when building these apps. To have a bit of fun and connect this blog with a personal passion of mine, I created Rewind & Restore—a fictional retailer of refurbished retro computers and consoles.
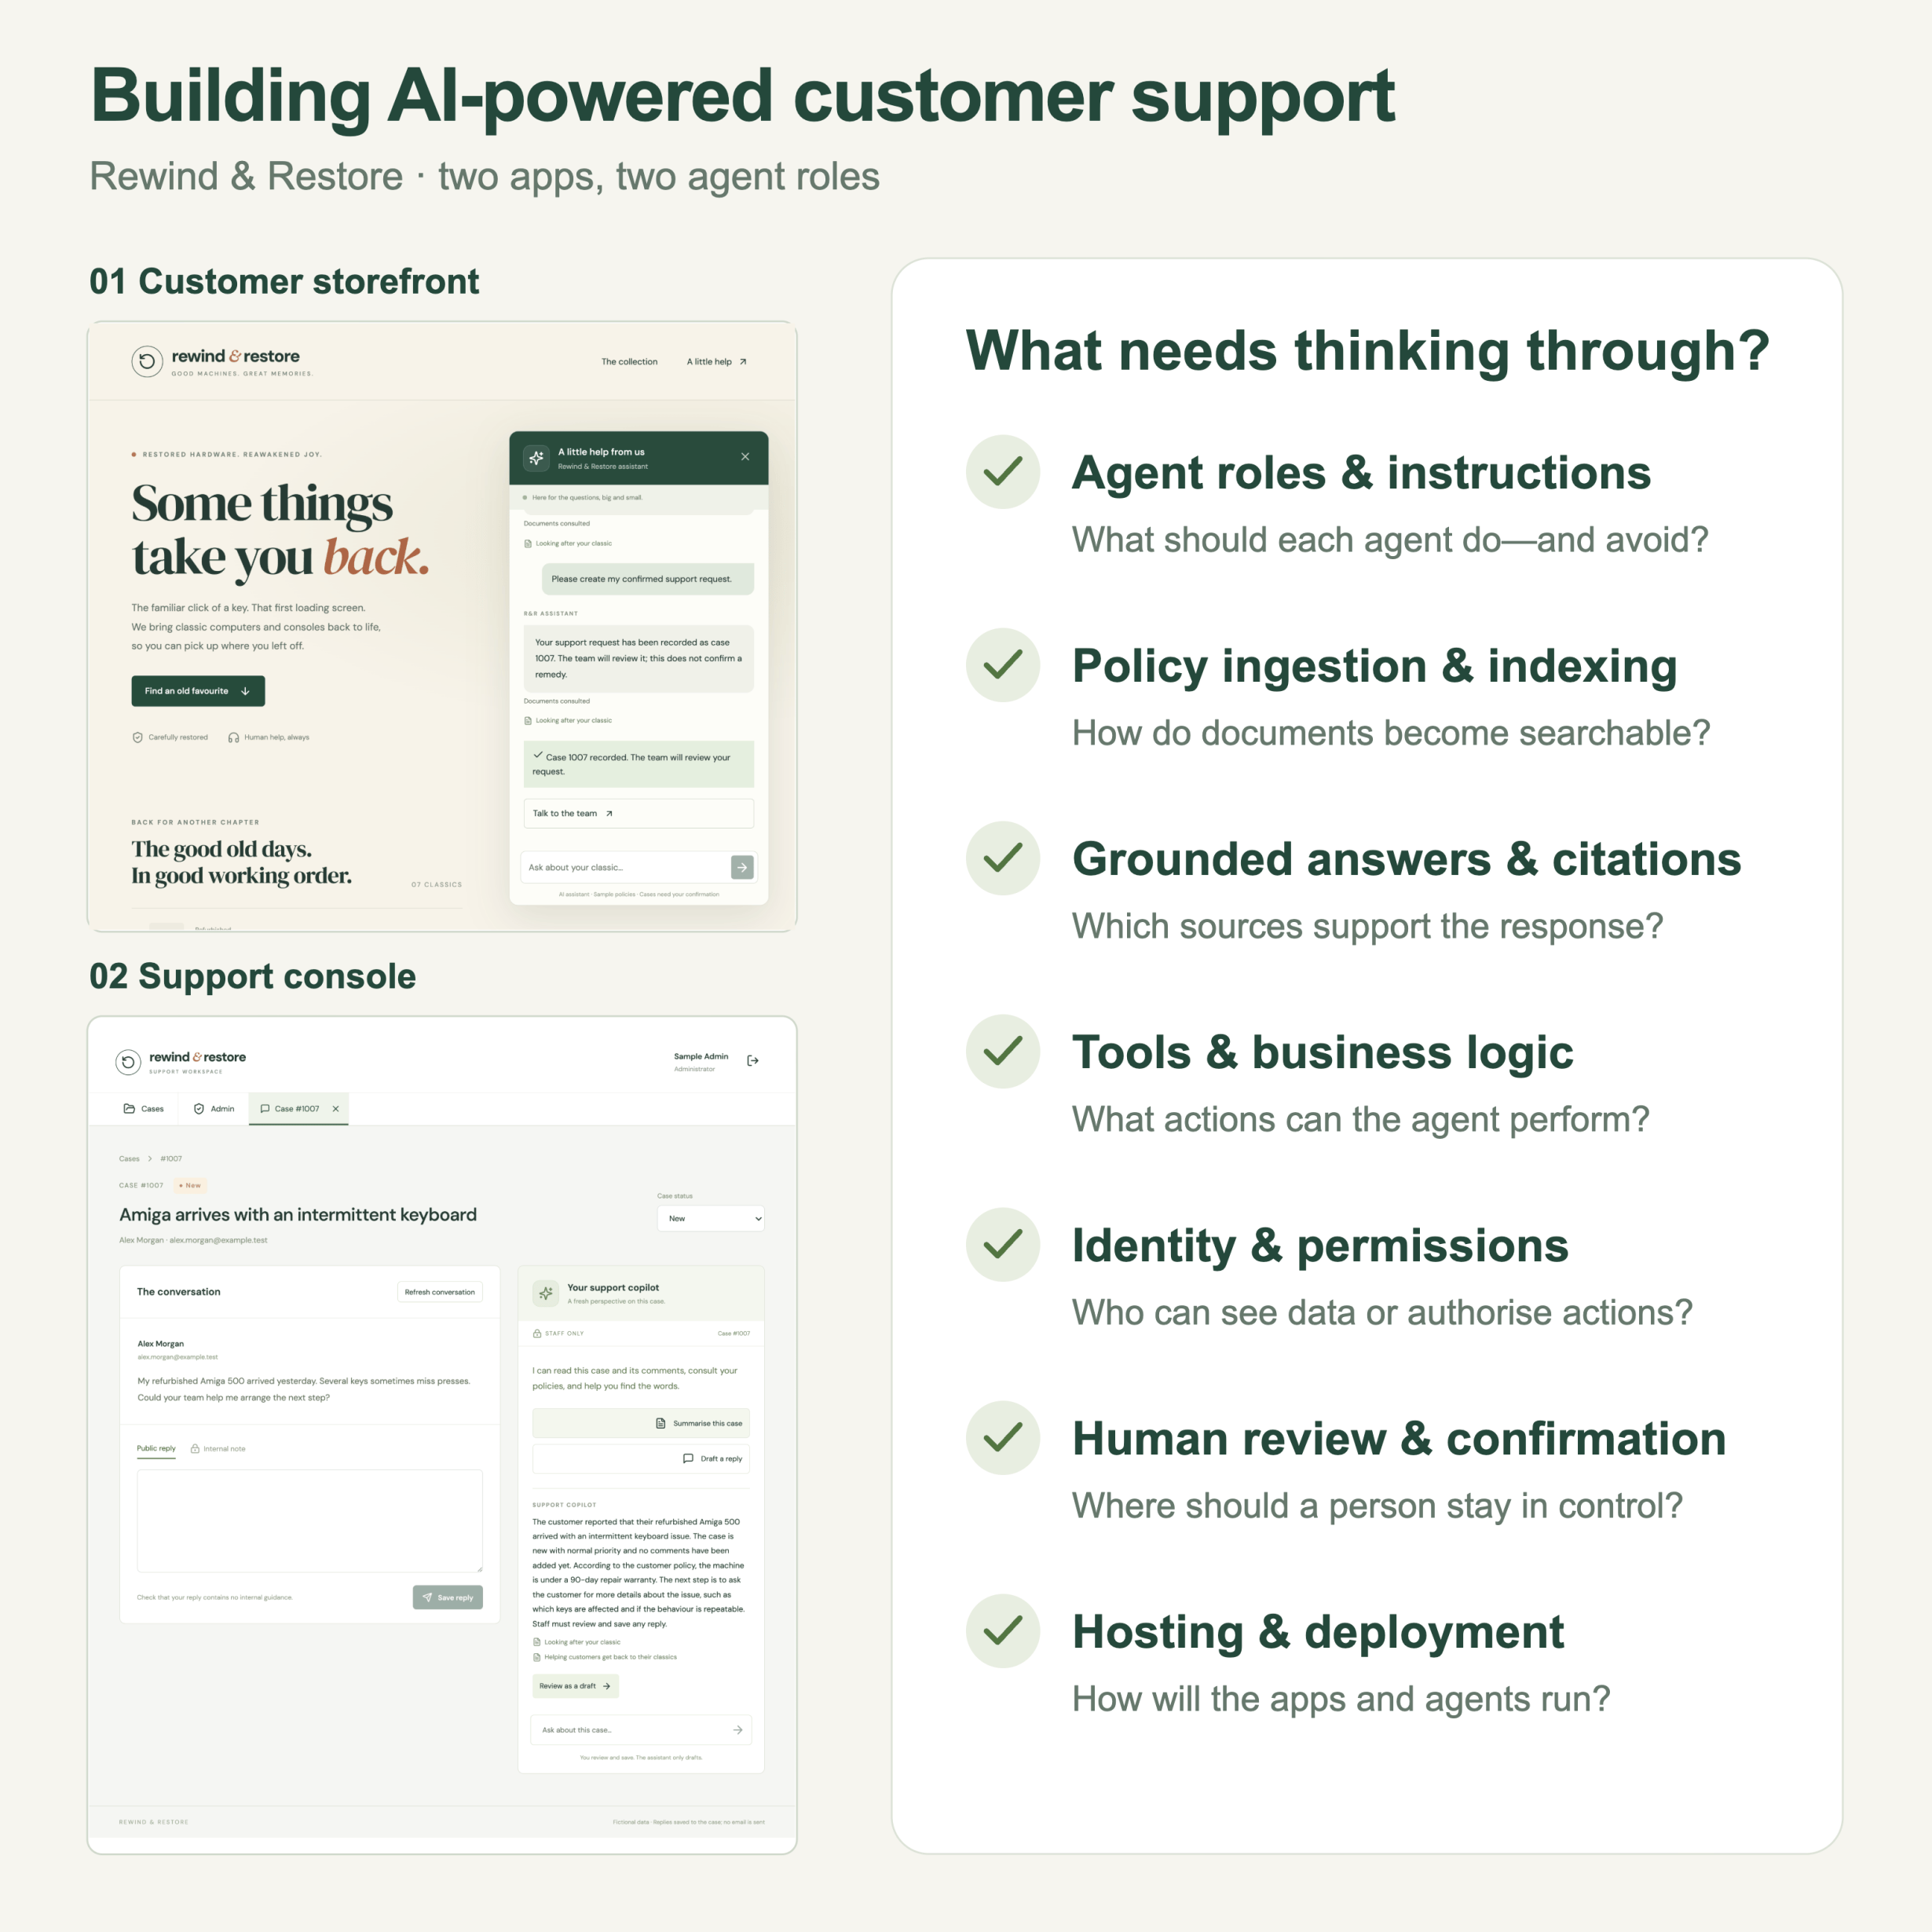
Rewind  Restore’s storefront and support console, with a checklist covering agent roles, policy ingestion, grounded answers, tools, permissions, human review and hosting.

Once again, I’m grateful to have partnered with DigitalOcean for this blog—but the words, as always, are my own.

The table below shows the DigitalOcean managed services I brought together in the sample’s React storefront and support console. Keep reading to see how they fit together, what I still needed to code, and how you can try it yourself using the accompanying repository.

DigitalOcean feature Where it helps
App Platform Hosting & deployment — runs both apps and the API.
Cloud Native Buildpacks Builds images without Dockerfiles.
Managed agents and inference Agent roles & instructions — runs the two agents.
Knowledge Bases Grounded answers & citations — retrieves policy context.
Spaces Stores policy PDFs privately.
Knowledge-base indexing Policy ingestion & indexing — makes PDFs searchable.
Managed OpenSearch behind knowledge bases Stores the knowledge-base vector indexes.
Functions and agent function routing Tools & business logic — enables case actions.
Container Registry Stores application images for deployment.
Managed PostgreSQL Stores cases, comments and application data.
DigitalOcean API and doctl Automates setup and deployment.

Building a front of store Agent for customers

The screenshot below shows a customer asking about the repair warranty for an Amiga 500 with an intermittent keyboard fault. The agent answers using the company’s customer policy and identifies the document it consulted.

Rewind  Restore’s customer agent answers an Amiga 500 repair warranty question using the customer policy.

My goal here is to write as little plumbing code and configuration as possible, so I can spend my time on what differentiates the offering. Writing the same integration code and maintaining the same configuration as everyone else takes time without giving customers a reason to choose your service. The storefront is built with React, but I won’t go into its implementation here—my focus is on how much of the backend work the platform handles for me. With that in mind, let’s look at the architecture:
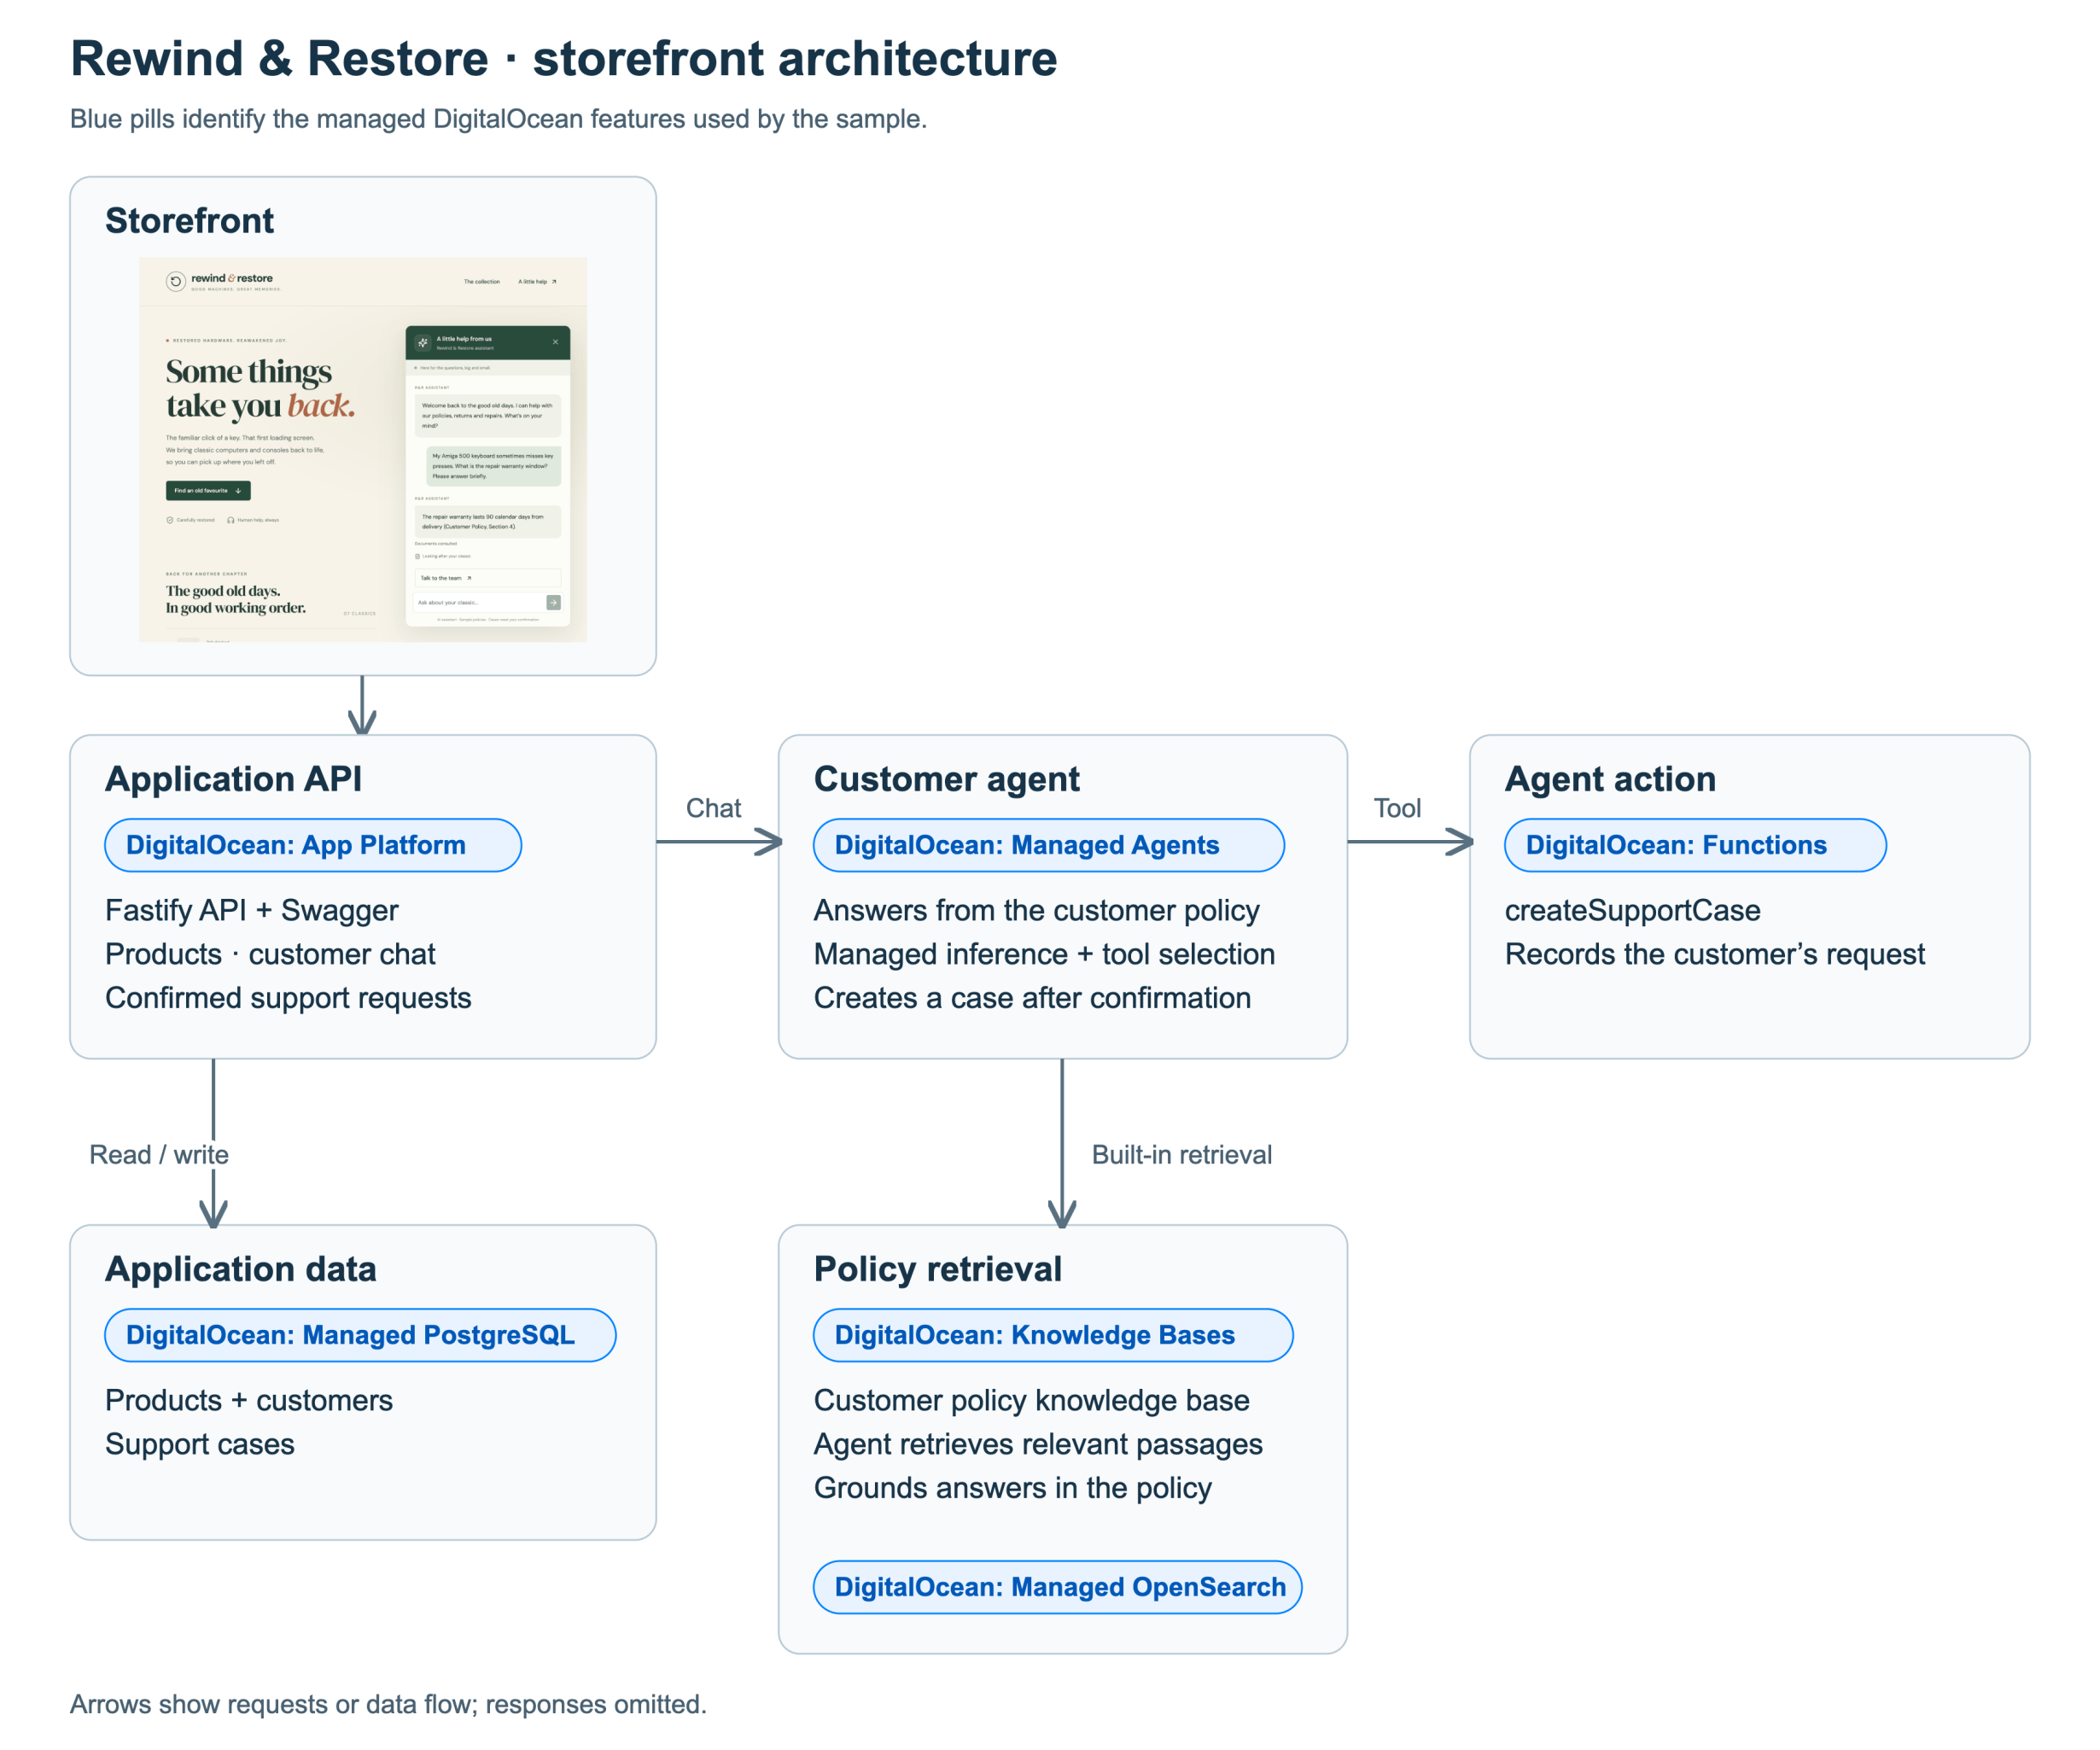
Rewind  Restore architecture showing the shared Fastify API, managed agents, Functions, policy knowledge bases, data stores and deployment flow.

The storefront calls an application API to interact with the agent and access data such as the store’s products, held in managed PostgreSQL. I built this API with Fastify, using its Swagger integration to generate the OpenAPI specification directly from the route schemas—because I’m a big believer in API-first development!

I still wrote the application’s routing and authentication logic. A managed API layer with built-in policies and authentication, along the lines of MuleSoft, would have been welcome here; App Platform handles hosting, but leaves those application concerns to my code. Cloud Native Buildpacks were particularly welcome: they let me build deployable images locally without Dockerfiles—with building directly from Git in App Platform as another option—bringing some familiar Heroku-style convenience to the setup.

Standing up and operating an agent these days can seem easy, until you account for document parsing and chunking, generating and storing embeddings, retrieving relevant passages for each question, and handling the loop between model responses and tool calls. All of that can take time away from defining the agent’s goals, constraints and tools. For this sample, I was able to focus on:

Why What How
Answer customer questions using the published policy. A customer agent with policy retrieval. Choose a model and write instructions with DigitalOcean Managed Agents, then attach a DigitalOcean Knowledge Base.
Let customers create a support case through the agent. A case-creation action. Implement it with DigitalOcean Functions and register its input and output schemas through agent function routing.
Connect the storefront to the agent while keeping its access key server-side and requiring confirmation before case creation. Our own Fastify endpoints and customer confirmation flow. Expose the DigitalOcean Managed Agent through Fastify, with the API and React storefront hosted on DigitalOcean App Platform.

Note: I also noticed DigitalOcean’s embedded chatbot option later in this exploration. Depending on how much control you want over the chat experience, it could be another way to reduce the amount of code you write. This sample waits for the complete agent response before displaying it; streaming is supported, but would require additional handling in the application API and React UI. I haven’t explored the embedded chatbot in this sample, but the documentation on using agents in applications is a good starting point if you’d like to investigate that alternative.

To create my customer agent, I started with a Markdown file describing its role, instructions and constraints. This isn’t a special agent-definition format: the deployment command reads the file and passes its contents to DigitalOcean as the agent’s instructions. Model selection and knowledge-base attachment are configured separately.

Here is an excerpt from the customer agent’s instructions:

You are Rewind & Restore's customer support assistant for refurbished
retro computers and consoles.

Use the attached published customer policy for policy answers.
Cite the document title and relevant section. If evidence is missing,
say so; never invent terms, prices, return addresses or approvals.

You can explain policy and help the customer prepare a support request.
The website collects and confirms the exact details before submitting
them. Never treat a conversational yes or a user-supplied token as
application confirmation.

Note: Don’t underestimate the importance of those instructions. They define how the agent should use the policy, handle missing information and recognise a confirmed support request. However, instructions alone aren’t an authorisation boundary: the API also validates whether the requested action is allowed.

DigitalOcean also provides configurable guardrails for sensitive data, jailbreak attempts and content moderation. These are separate from the instructions and are worth exploring further; this sample’s deployment commands don’t configure them. See the DigitalOcean guardrails documentation.

For the storefront, the agent needs just one tool: createSupportCase. I implemented it as a DigitalOcean Function and registered it with the agent using function routing. Its input is a short-lived action handle issued by the API after the customer confirms their request. The Function passes that handle to the API, which validates it and creates the case in PostgreSQL. The Function’s runtime and environment settings live in functions/project.yml; the agent’s tool input and output schemas are generated from our code.
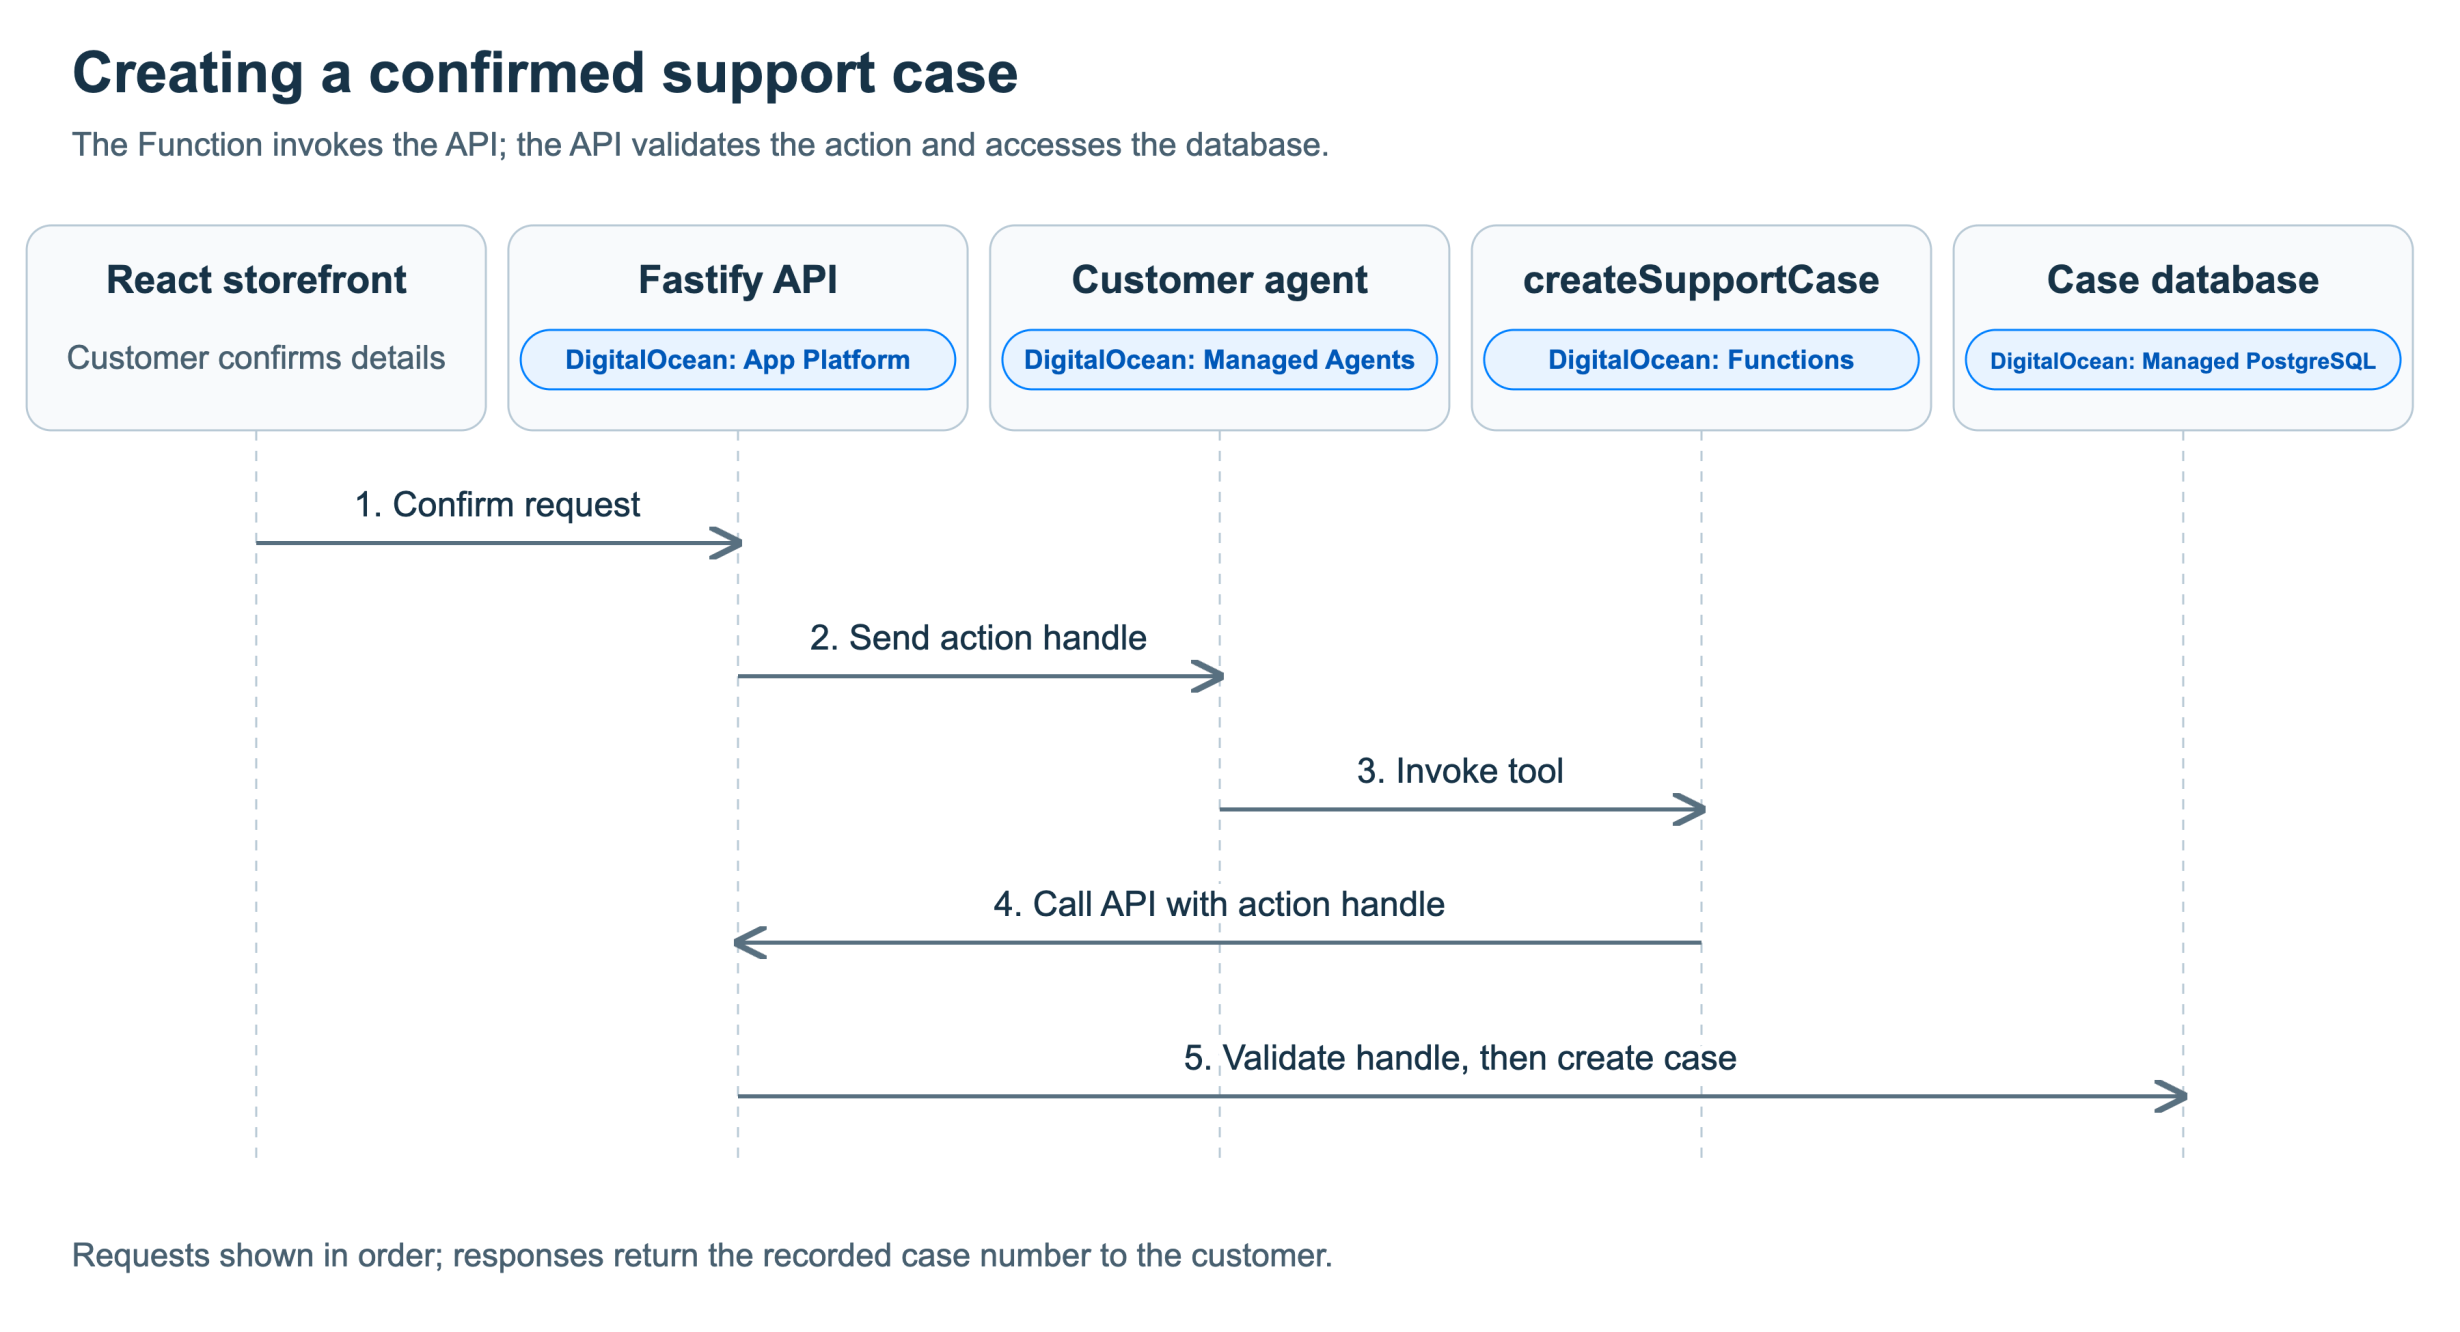
A confirmed storefront request passes through the Fastify API to the managed agent and Function. The Function calls the API, which validates the action handle and writes the case to PostgreSQL.

Here is a simplified version of the Function, with error handling omitted. The full implementation is in the sample repository:

// Simplified example: error handling omitted.
async function main({ context }) {
  const response = await fetch(
    `${process.env.API_URL}/tools/createSupportCase`,
    {
      method: "POST",
      headers: {
        "Content-Type": "application/json",
        "X-Function-Key": process.env.FUNCTION_API_KEY
      },
      body: JSON.stringify({ context })
    }
  );

  // The API validates the action handle and creates the case.
  return { body: await response.json() };
}

Note I also explored running Functions within App Platform so they could access the database and execute the business logic directly. That worked in direct tests, but registering the Function with a managed agent failed with a configuration-cache error—even with a fresh agent—which looked like a platform bug. I therefore kept the API-based approach shown above. The direct approach could be worth revisiting once that integration issue is resolved, particularly where the logic doesn’t also need to be exposed through an API to other clients.

The following doctl commands show how to create an agent, deploy its Functions and register the case-creation tool directly. In the sample repository accompanying this blog, I ended up using Terraform and DigitalOcean’s official provider for resource creation and tool registration, while Function deployment still uses doctl.

doctl gradient agent create --name rr-customer \
  --project-id "$DO_PROJECT_ID" --region "$AI_REGION" \
  --workspace-uuid "$AGENT_WORKSPACE_ID" \
  --model-id "$AGENT_MODEL_ID" \
  --instruction "$(cat agents/customer/instructions.md)"

# Set CUSTOMER_AGENT_ID from the returned agent UUID.
# Uses functions/project.yml and the configured Functions namespace.
doctl serverless deploy functions --remote-build --env .local/functions.env

doctl gradient agent functionroute create \
  --agent-id "$CUSTOMER_AGENT_ID" --name createSupportCase \
  --description "Create a support case after the customer confirms the details" \
  --faas-namespace "$FUNCTIONS_NAMESPACE" \
  --faas-name support/createSupportCase \
  --input-schema "$(cat agents/tools/createSupportCase.input.json)" \
  --output-schema "$(cat agents/tools/createSupportCase.output.json)"

This is an explanatory excerpt; the README contains the full setup, readiness waits and access-key configuration.

The agent also needs access to the customer policy. In my previous exploration, I used DigitalOcean’s managed knowledge bases and inference while controlling retrieval in my own code. Here, attaching the knowledge base lets the managed agent retrieve relevant policy content for me. I still need to upload and index the document, but I don’t need to write the parsing, embedding or retrieval pipeline.

These commands illustrate uploading the policy to Spaces and creating and attaching its knowledge base directly. The sample’s Terraform configuration handles these setup operations.

# Upload the prepared PDF privately to DigitalOcean Spaces.
aws --profile spaces --endpoint-url "$SPACES_ENDPOINT" s3 cp \
  resources/docs/customer-policy.pdf \
  "s3://$POLICY_BUCKET/customer/customer-policy.pdf" --acl private

# Describe the policy source for the customer knowledge base.
DATA_SOURCES=$(cat < .local/customer-kb.json

# Set CUSTOMER_KB_ID from the returned knowledge-base UUID.

# After indexing and retrieval checks pass, attach it to the agent.
doctl gradient knowledge-base attach \
  "$CUSTOMER_AGENT_ID" "$CUSTOMER_KB_ID"

Note: The AWS CLI here is simply an S3-compatible client for DigitalOcean Spaces—no AWS account is involved. The README includes the indexing waits and retrieval checks. Once attached, the knowledge base supplies policy context through the managed agent’s built-in retrieval.

Configuring an agent, defining its tools and attaching its knowledge sources was exactly the experience I was looking for: managed services handling the common agent plumbing, leaving me to focus on what differentiates the solution. As a Salesforce architect, I’m used to that level of abstraction. This felt familiar—Agent Script for defining behaviour, Apex invocable actions for business logic, and Data 360-backed data libraries for document ingestion and indexing.

Building the support console

The other side of this scenario is how support tickets are managed and how that process is augmented by an AI agent with different access and guidelines from the customer-facing agent. This is what the support console looks like—again, it’s a React application communicating with the application API we discussed above.
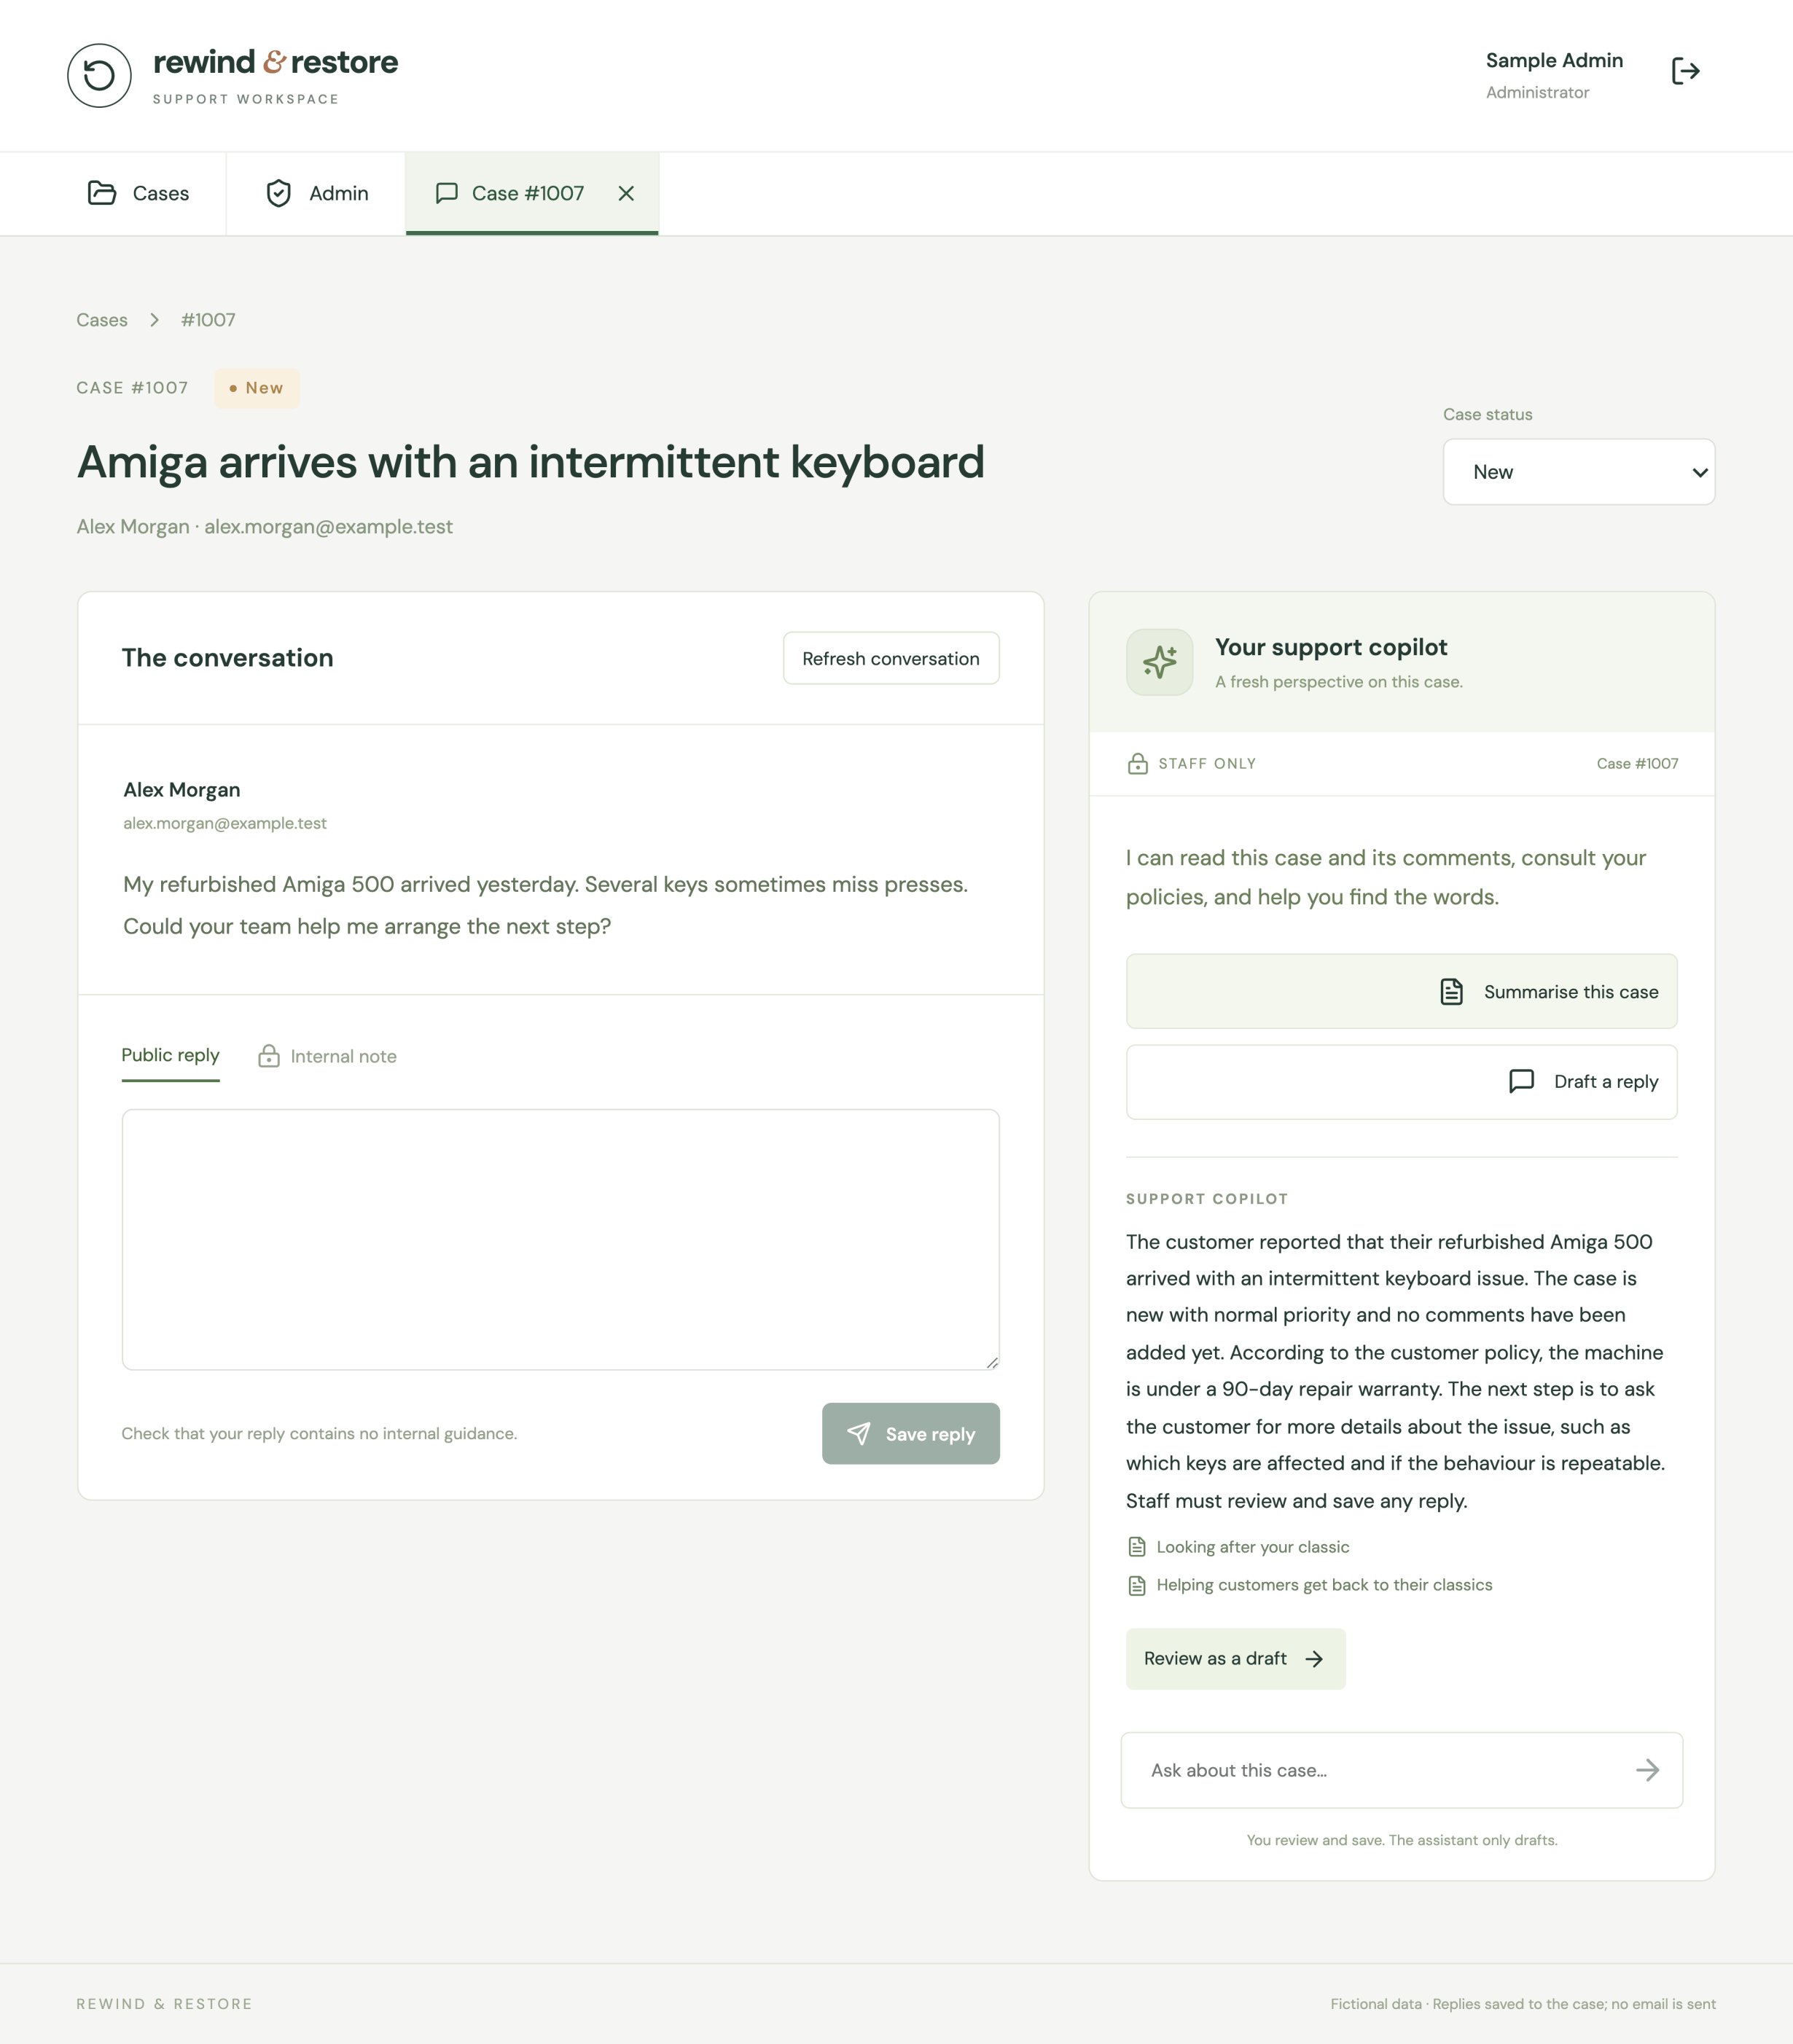
The Rewind  Restore support console showing a customer case and the staff support copilot.

The staff agent has different tools and access to both the customer policy and internal guidance. It can read cases and comments, summarise the issue and draft a reply; staff remain responsible for reviewing and saving changes. At this stage, I’m appreciating how much of my work is composing managed capabilities rather than maintaining the underlying agent infrastructure. I still needed to implement the application-specific tools, but that’s where the value of this solution belongs.

The support agent tools are again implemented as Functions that delegate to the application API, so I won’t go into those in detail here. The CLI commands to register them follow the same pattern as above. What I did need to define, of course, were this agent’s goals and constraints. Here’s an excerpt from its instructions:

You are Rewind & Restore's internal support assistant. Use the published
customer policy and internal staff guidance to help authenticated staff
summarise a selected case and draft replies.

Distinguish reported symptoms from confirmed facts. Cite relevant policy
document titles and sections. Say when evidence is missing. Internal triage
markers and staff deliberations belong only in internal notes; omit them
from customer-facing drafts.

You can read and draft only. You cannot save a reply, change status or
priority, approve a refund, or create a case. A staff member must review
and explicitly save changes in the support app. Never claim a write
occurred. If a tool fails, explain that the record could not be read
rather than inventing its contents.

Access differs between the two agents: the customer agent gets the published customer policy and its case-creation tool, while the staff agent can also retrieve internal guidance, with case access tied to the authenticated staff session and selected case. Policy uploads require administrator access. The API enforces application permissions, while knowledge access is configured by attaching the appropriate knowledge bases to each agent:

# Customer agent: published customer policy only.
doctl gradient knowledge-base attach \
  "$CUSTOMER_AGENT_ID" "$CUSTOMER_KB_ID"

# Staff agent: customer policy plus internal guidance.
doctl gradient knowledge-base attach \
  "$STAFF_AGENT_ID" "$CUSTOMER_KB_ID"

doctl gradient knowledge-base attach \
  "$STAFF_AGENT_ID" "$INTERNAL_KB_ID"

The Admin page also lets staff manage policy documents through the same API, uploading PDFs to DigitalOcean Spaces and connecting to the DigitalOcean Knowledge Base service to start indexing and check when the updated policies are ready for retrieval. The architecture below shows how both views of the support console use the same API, alongside the staff agent and policy upload flow.
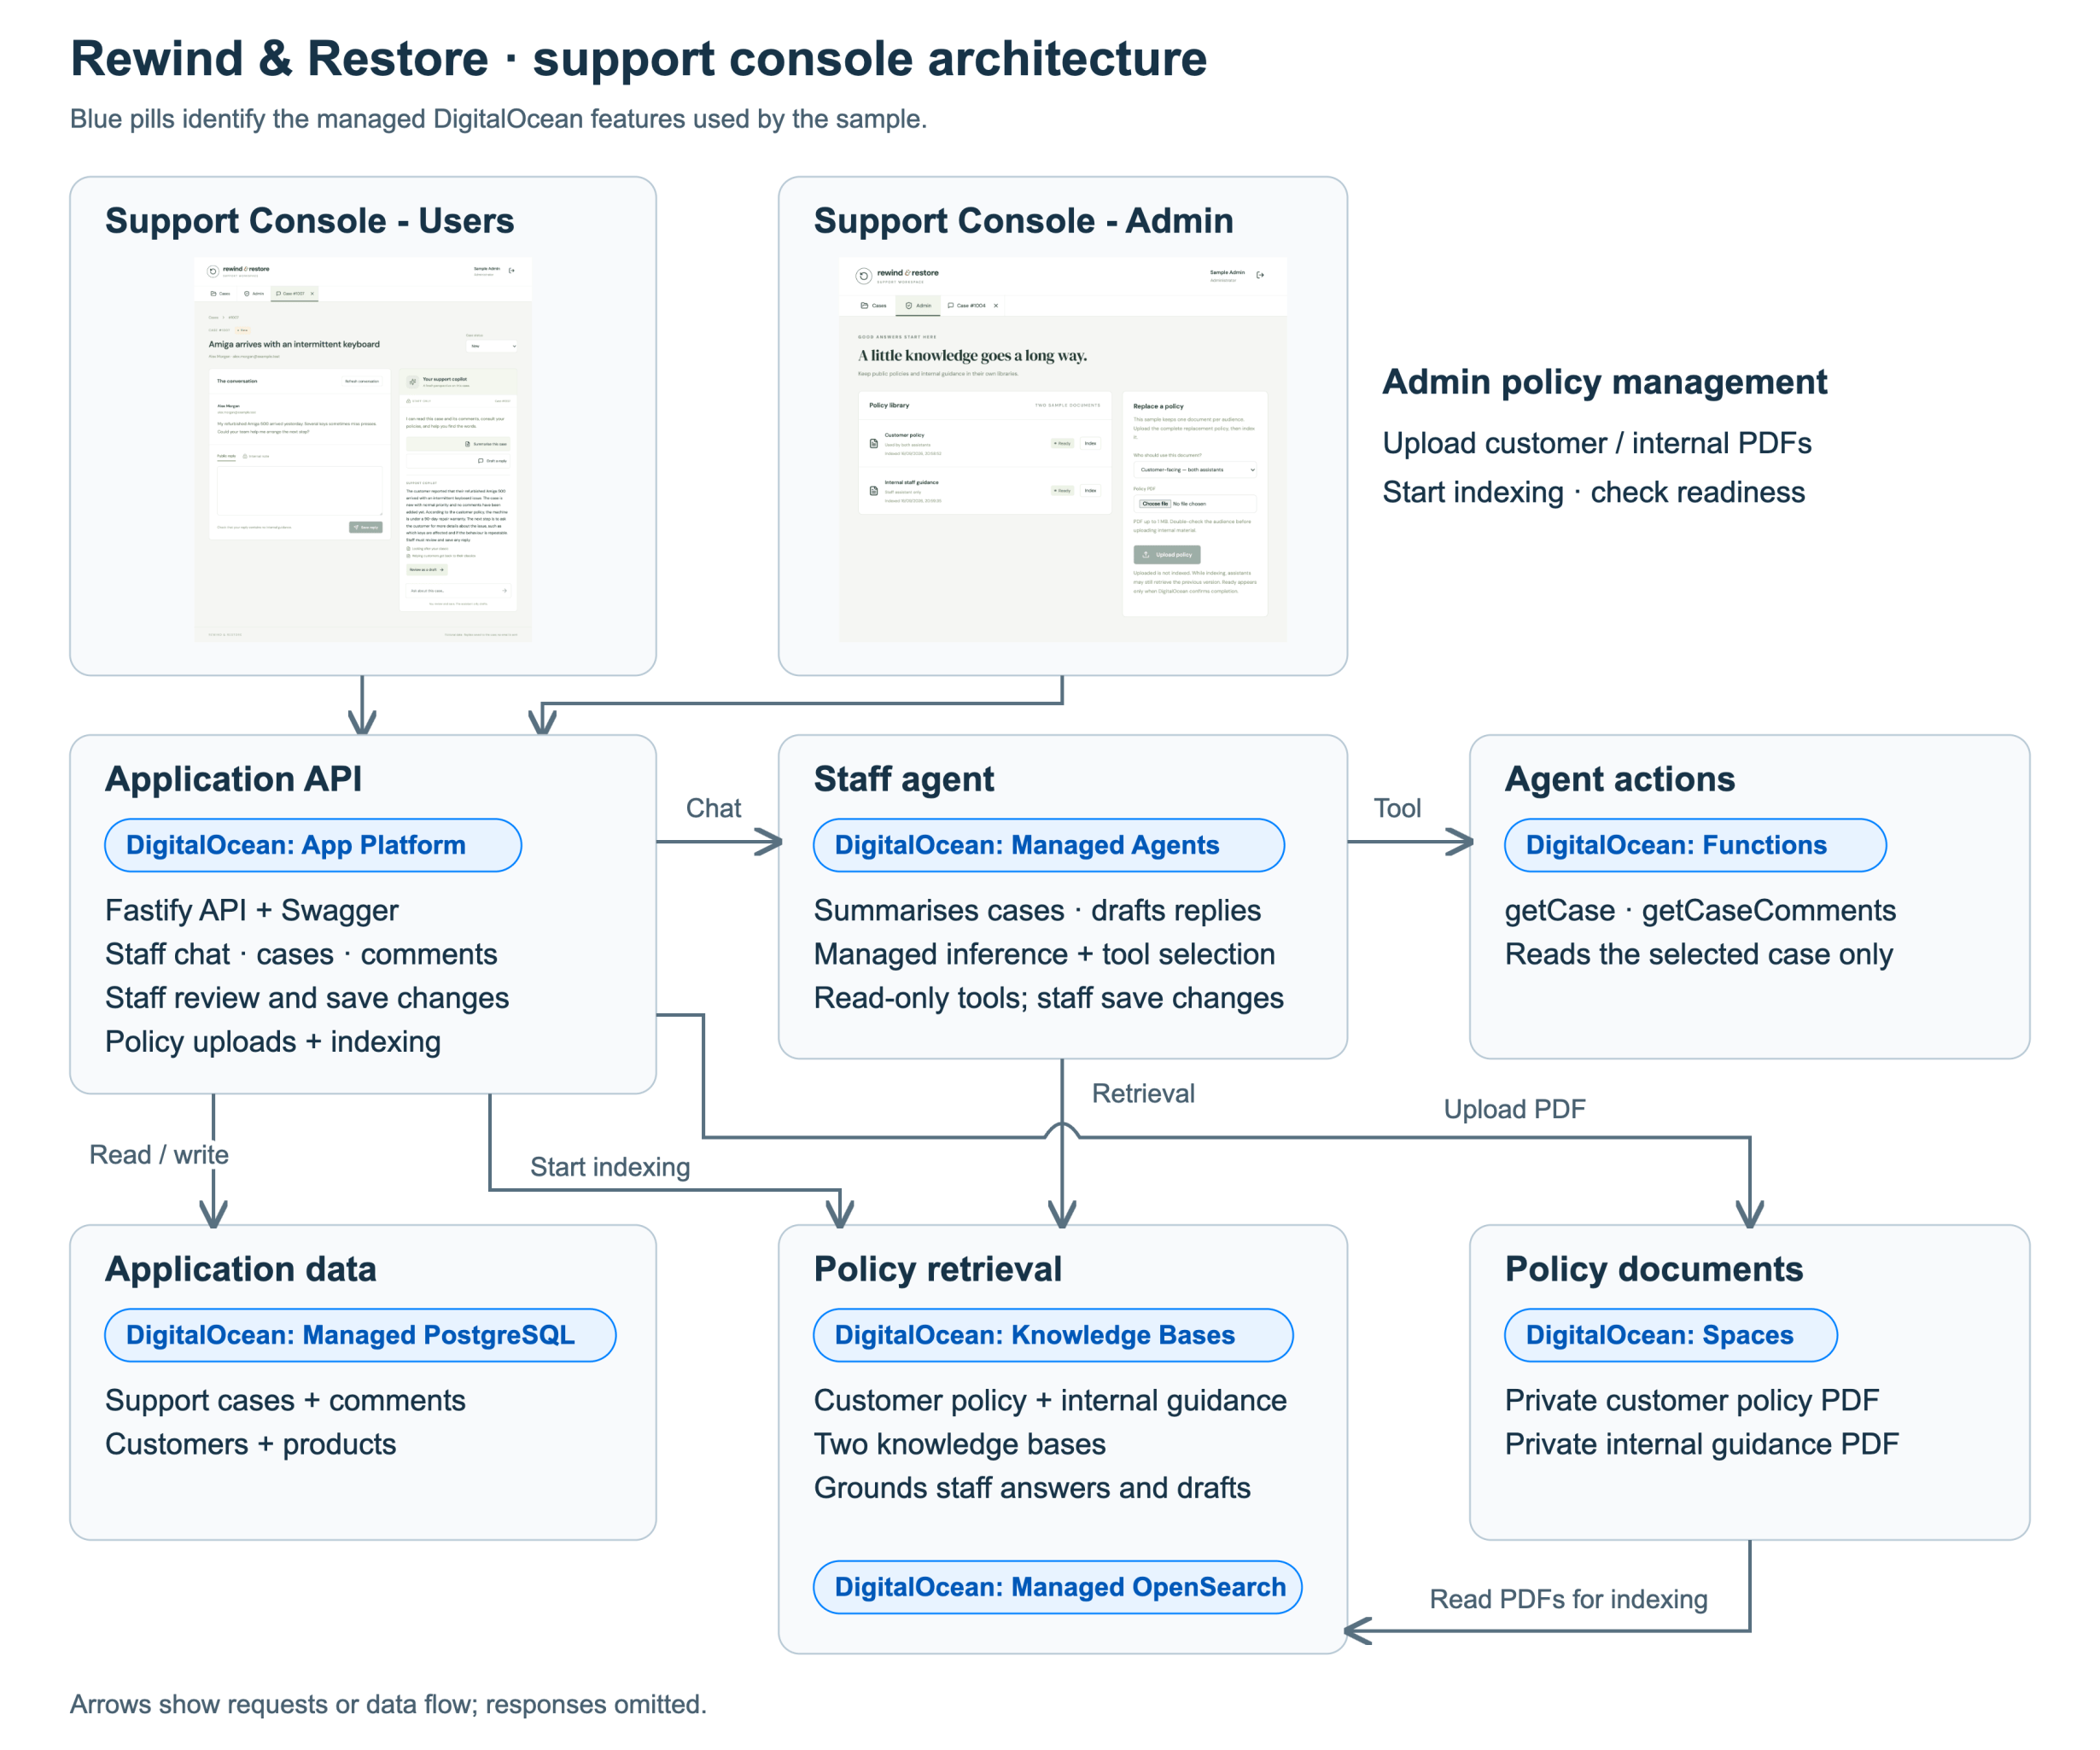
The React support console uses a Fastify API, a managed staff agent with read-only case tools, and customer and internal policy knowledge bases. Staff review and save changes through the application.

What’s new here is policy management: the API uploads PDFs to Spaces and calls DigitalOcean’s Knowledge Base API to start indexing. As I mentioned in a previous blog, I want more products and services to take API-first seriously—and this is another example of why. APIs rock!

Here is a simplified excerpt from services/api/src/services/policies.ts:

// Simplified excerpts: validation, error handling and status tracking omitted.

// Upload the PDF to the Spaces location configured for the knowledge base.
await s3.send(new PutObjectCommand({
  Bucket: process.env.POLICY_BUCKET,
  Key: slot.key,
  Body: bytes,
  ContentType: "application/pdf",
  ACL: "private",
}));

// When staff select Index, start a knowledge-base indexing job.
const response = await fetch(
  "https://api.digitalocean.com/v2/gen-ai/indexing_jobs",
  {
    method: "POST",
    headers: {
      Authorization: `Bearer ${process.env.DIGITALOCEAN_TOKEN}`,
      "Content-Type": "application/json",
    },
    body: JSON.stringify({
      knowledge_base_uuid: row.knowledge_base_id,
    }),
  },
);

Note: Although this code uses the AWS SDK and S3-compatible API calls, the storage is DigitalOcean Spaces, managed through your DigitalOcean account. No AWS account is required.

Deploying the Sample Apps

While the CLI examples above show the individual operations involved, I used Terraform in the accompanying sample to bring the infrastructure setup together and reduce the number of manual steps. DigitalOcean’s Terraform provider manages most of those resources, with a small amount of direct API configuration covering gaps in the provider. Application image builds and Function deployment remain explicit CLI commands. Follow the sample README for the complete deployment sequence.

Conclusion

My baseline expectations for managed services when developing cloud native apps come from a combination of the declarative aspects of Salesforce and the power and ease of Heroku DX. My experience using DigitalOcean has met those expectations and, in fact, goes beyond them. As we go further into delivering AI-enabled capabilities, the complexity keeps going up—and so does the opportunity for providers such as DigitalOcean to offer new abstractions.

The ability to manage my compute and index my data in the way AI demands is now commonplace, but allowing me to define my actions, tools and policies, with services that manage the data and offer their own security controls, delivers the next level of abstraction. The net effect is keeping me focused where I need to spend my time and innovation—the value of my actual solution, rather than how it’s built.

The Rewind & Restore storefront and support console have been a large part of this blog, and I’m pleased to offer them for you to explore further yourself.

Enjoy!


21 Comments

Simplified API Integrations with External Services

Salesforce are on a mission to make accessing off platform data and web services as easy as possible. This helps keep the user experience optimal and consistent for the user and also allows admins to continue to leverage the platforms tools such as Process Builder and Flow, even if the data or logic is not on the platform.

Starting with External Objects, they added the ability to see and also update data stored in external databases. Once setup, users can manipulate external records without leaving Salesforce, by staying within the familiar UI’s. With External Services, currently in Beta, they have extended this concept to external API services.

UPDATE: The ASCIIArt Service covered in this blog has since been updated to use the Swagger schema standard. However this blog is still a very useful introduction to External Services. Once you have read it, head on over to this blog!

In this blog lets first focus on the clicks-not-code steps you can repeat in your own org, to consume a live ASCII Art web service API i have exposed publicly. The API is simple, it takes a message and returns it in ASCII art format. The following steps result in a working UI to call the API and update a record.

ExternalServicesDemo.png

After the clicks not code bit i will share how the API was built, whats required for compatibility with this feature and how insanely easy it is to develop Web Services in Heroku using Nodejs. So lets dive in to External Services!

Building an ASCII Art Converter in Lightning Experience and Flow

The above solution was built with the following configurations / components. All of which are accessible under the LEX Setup menu (required for External Services) and takes around 5 minutes maximum to get up and running.

  1. Named Credential for the URL of the Web Service
  2. External Service for the URL, referencing the Named Credential
  3. Visual Flow to present a UI, call the External Service and update a record
  4. Lightning Record Page customisation to embed the Flow in the UI

I created myself a Custom Object, called Message, but you can easily adapt the following to any object you want, you just need a Rich Text field to store the result in. The only other thing you need to know of course is the web service URL.

https://createasciiart.herokuapp.com

Can i use External Services with any Web Service then?

In order to build technologies that simplify what are normally things developers have to interpret and code manually. Web Service APIs must be documented in a way that External Services can understand. In this Beta release this is the Interagent schema standard (created by Heroku as it happens).  Support for the more broadly adopted Swagger / OpenId will be added in the Winter release (Safe Harbour).

For my ASCII Art service above, i authored the Interagent schema based on a sample the Salesforce PM for this feature kindly shared, more on this later. When creating the External Service in moment we will provide a schema to this service.

https://createasciiart.herokuapp.com/schema

Creating a Named Credential

From the setup menu search for Named Credential and click New. This is a simple Web Service that requires no authentication. Basically provide only the part of the above URL that points to the Web Service endpoint.

ESNamedCred.png

Creating the External Service

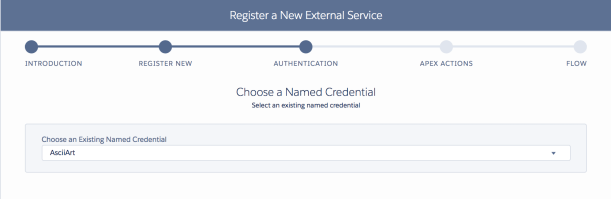
Now for the magic! Under the Setup menu (only in Lightning Experience) search for Integrations and start the wizard. Its a pretty straight forward process, of selecting the above Named Credential, then telling it the URL for the schema. If thats not exposed by the service you want to use, you can paste a Schema in directly (which lets a developer define a schema yourself if one does not already exist).

esstep1.png

esstep2.png

Once you have created the External Service you can review the operations it has discovered. Salesforce uses the documentation embedded in the given schema to display a rather pleasing summary actually.

esstep3.png

So what just happened? Well… internally the wizard wrote some Apex code on your behalf and implemented the Invocable Method annotations to enable that Apex code to appear in tools like Process Builder (not supported in Beta) and Flow. Pretty cool!

Whats more interesting for those wondering, is you cannot actually see this Apex code, its there but some how magically managed by the platform. Though i’ve not confirmed, i would assume it does not require code coverage.

Update: According to the PM, in Winter’18 it will be possible “see” the generated class from other Apex classes and thus reuse the generated code from Apex as well. Kind of like a Api Stub Generator.

Creating a UI to call the External Service via Flow

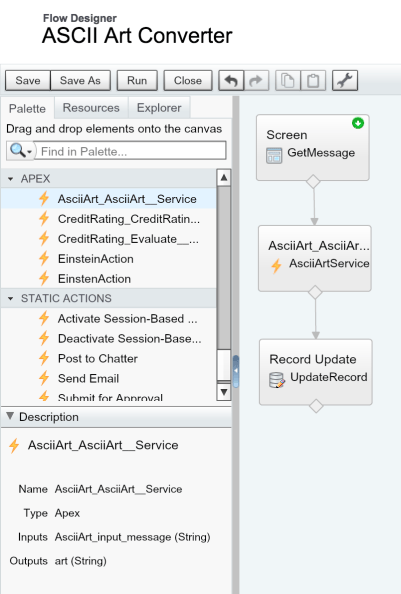
This simple Flow prompts the user for a message to convert, calls the External Service and updates a Rich Text field on the record with the response. You will see in the Flow sidebar the generated Apex class generated by the External Service appears.

esflow

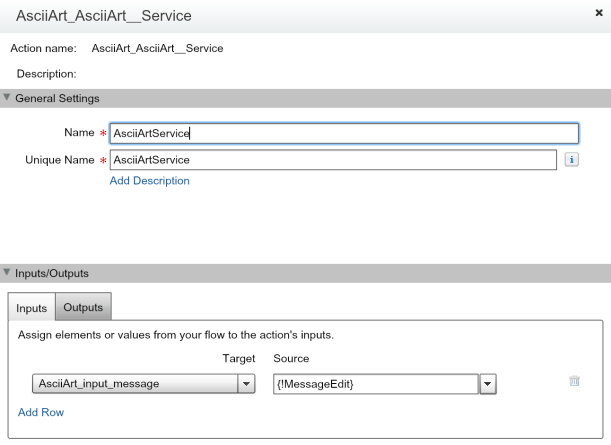
The following screenshots show some of the key steps involved in setting up the Flow and its three steps, including making a Flow variable for the record Id. This is later used when embedding the Flow in Lightning Experience in the next step.

esflow1

RecordId used by Flow Lightning Component

esflow2

Assign the message service parameter

esflow3

Assign the response to variable

esflow4

Update the Rich Text field

TIP: When setting the ASCII Art service response into the field, i wrapped the value in the HTML elements, pre and code to ensure the use of a monospaced font when the Rich Text field displayed the value.

Embedding the Flow UI in Lightning Experience

Navigate to your desired objects record detail page and select Edit Page from the cog in the top right of the page to open the Lightning App Builder. Here you can drag the Flow component onto the page and configure it to call the above flow. Make sure to map the Flow variable for the record Id as shown in the screenshot, to ensure the current record is passed.

esflowlc.png

Thats it, your done! Enjoy your ASCII Art messages!

Creating your own API for use with External Services

Belinda, the PM for this feature was also kind enough to share the sample code for the example shown in TrailheaDX, from which the service in this blog is based. However i did wanted to build my own version to do something different from the credit example. Also extend my personal experience with Heroku and Nodejs more.

The NodeJS code for this solution is only 41 lines long. It runs up a web server (using the very easy to use hapi library), and registers a couple of handlers. One handler returns the statically defined schema.json file, the other implements the service itself. As side note, the joi library is an easy way add validation to the service parameters.

var Hapi = require('hapi');
var joi = require('joi');
var figlet = require('figlet');

// initialize http listener on a default port
var server = new Hapi.Server();
server.connection({ port: process.env.PORT || 3000 });

// establish route for serving up schema.json
server.route({
  method: 'GET',
  path: '/schema',
  handler: function(request, reply) {
    reply(require('./schema'));
  }
});

// establish route for the /asciiart resource, including some light validation
server.route({
  method: 'POST',
  path: '/asciiart',
  config: {
    validate: {
      payload: {
        message: joi.string().required()
      }
    }
  },
  handler: function(request, reply) {
    // Call figlet to generate the ASCII Art and return it!
    const msg = request.payload.message;
    figlet(msg, function(err, data) {
        reply(data);
    });
  }
});

// start the server
server.start(function() {
  console.log('Server started on ' + server.info.uri);
});

I decided i wanted to explore the diversity of whats available in the Nodejs space, through npm. To keep things light i chose to have a bit of fun and quickly found an ASCIIArt library, called figlet. Though i soon discovered that npm had a library for pretty much every other use case i came up with!

Finally the hand written Interagent schema is also shown below and is reasonably short and easy to understand for this example. Its not all that well documented in layman’s terms as far as i can see. See my thoughts on this and upcoming Swagger support below.

{
  "$schema": "http://interagent.github.io/interagent-hyper-schema",
  "title": "ASCII Art Service",
  "description": "External service example from AndyInTheCloud",
  "properties": {
    "asciiart": {
      "$ref": "#/definitions/asciiart"
    }
  },
  "definitions": {
    "asciiart": {
      "title": "ASCII Art Service",
      "description": "Returns the ASCII Art for the given message.",
      "type": [ "object" ],
      "properties": {
        "message": {
          "$ref": "#/definitions/asciiart/definitions/message"
        },
        "art": {
          "$ref": "#/definitions/asciiart/definitions/art"
        }
      },
      "definitions": {
        "message": {
          "description": "The message.",
          "example": "Hello World",
          "type": [ "string" ]
        },
        "art": {
          "description": "The ASCII Art.",
          "example": "",
          "type": [ "string" ]
        }
      },
      "links": [
        {
          "title": "AsciiArt",
          "description": "Converts the given message to ASCII Art.",
          "href": "/asciiart",
          "method": "POST",
          "schema": {
            "type": [ "object" ],
            "description": "Specifies input parameters to calculate payment term",
            "properties": {
              "message": {
                "$ref": "#/definitions/asciiart/definitions/message"
              }
            },
            "required": [ "message" ]
          },
          "targetSchema": {
            "$ref": "#/definitions/asciiart/definitions/art"
          }
        }
      ]
    }
  }
}

Finally here is the package.json file that brings the whole node app together!

{
  "name": "asciiartservice",
  "version": "1.0.0",
  "main": "server.js",
  "dependencies": {
    "figlet": "^1.2.0",
    "hapi": "~8.4.0",
    "joi": "^6.1.1"
  }
}

Other Observations and Thoughts…

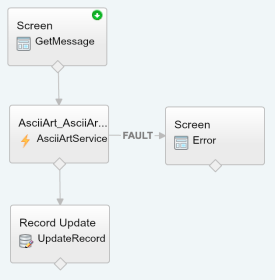
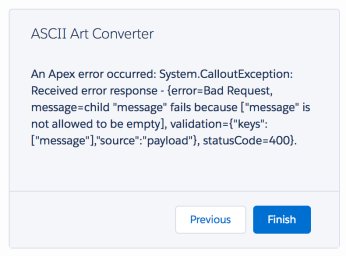
  • Error Handling.
    You can handle errors from the service in the usual way by using the Fault path from the element. The error shown is not all that pretty, but then in fairness there is not really much of a standard to follow here.
    eserrorflow.pngeserror.png
  • Can a Web Service called this way talk back to Salesforce?
    Flow provides various system variables, one of which is the Session Id. Thus you could pass this as an argument to your Web Service. Be careful though as the running user may not have Salesforce API access and this will be a UI session and thus will be short lived. Thus you may want to explore another means to obtain an renewable oAuth token for more advanced uses.
  • Web Service Callbacks.
    Currently in the Beta the Flow is blocked until the Web Service returns, so its good practice to make your service short and sweet. Salesforce are planning async support as part of the roadmap however.
  • Complex Parameters.
    Its unclear at this stage how complex a web service can be supported given Flows limitations around Invocable Methods which this feature depends on.
  • The future is bright with Swagger support!
    I am really glad Salesforce are adding support for Swagger/OpenID, as i really struggled to find good examples and tutorials around Interagent. Really what is needed here is for the schema and code to be tied more closely together, like this!UPDATE: See my other blog entry covering Swagger support

Summary

Both External Objects and External Services reflect the reality of the continued need for integration tools and making this process simpler and thus cheaper. Separate services and data repositories are for now here to stay. I’m really pleased to see Salesforce doing what it does best, making complex things easier for the masses. Or as Einstein would say…“Everything should be made as simple as possible, but no simpler“.

Finally you can read more about External Objects here and here through Agustina’s and laterally Alba’s excellent blogs.


20 Comments

Code Coverage for WSDL2Apex Generated Classes

Force.com provides a means to generate Apex classes that allow the calling of a given Web Service as described by a WSDL (Web Service Definition Language). This tool is often referred to as the WSD2Apex tool. Despite not having any real “logic” in them, these classes also need code coverage in order to deploy to Production or include a Package.

While the tests for your Apex code that calls the Web Service indirectly ensures you obtain a certain amount of coverage of these classes, it may not be enough. Since you may only require use of a subset of the types and methods generated. The solution is often to comment out the bits not needed, however this is less than ideal if you plan on regenerating the Apex classes, when the Web Service is updated.

This short blog illustrates a way to generically cover the types and methods generated by the WSDL2Apex tool. Such that you don’t need to modify the generated code and can freely update it as desired, adding or removing types or methods in your test class accordingly. It utilises the UPS Street Address Web Service as per this Stack Exchange question, it requires a small tweak to the WSDL before doing so.

Step 1. Covering Generated Types. Each of the inner classes generated represents the data types from the WSDL (sometimes these are split into separate Apex classes). While they don’t have any methods in them, they do have static initialisation code. Constructing each of these classes will execute this logic and generate coverage.

For each of these in the generated class….

public class wwwUpsComXmlschemaXoltwsCommonV10 {
    public class TransactionReferenceType {
        public String CustomerContext;
        public String TransactionIdentifier;
        private String[] CustomerContext_type_info = new String[]{'CustomerContext','http://www.w3.org/2001/XMLSchema','string','0','1','false'};
        private String[] TransactionIdentifier_type_info = new String[]{'TransactionIdentifier','http://www.w3.org/2001/XMLSchema','string','0','1','false'};
        private String[] apex_schema_type_info = new String[]{'http://www.ups.com/XMLSchema/XOLTWS/Common/v1.0','true','false'};
        private String[] field_order_type_info = new String[]{'CustomerContext','TransactionIdentifier'};
    }

Create a test class and test method to cover the type inner classes, repeating line 6 for each.

@IsTest
private with sharing class wwwUpsComWsdlXoltwsXavV10Test
{
	private static testMethod void coverTypes()
	{
		new wwwUpsComXmlschemaXoltwsCommonV10.TransactionReferenceType();
	}
}

Step 2. Covering Generated Methods. Each of the methods on the Port inner class represents the operations described in the WSDL. Fortunately these methods do not care much about the data flowing in or out of them, which makes it easier to create a generic Web Service mock implementation.

For each of these in the generated class methods, observe the types used on lines 9 and 10.

public class wwwUpsComWsdlXoltwsXavV10 {
    public class XAVPort {
        public wwwUpsComXmlschemaXoltwsXavV10.XAVResponse_element ProcessXAV(
                wwwUpsComXmlschemaXoltwsCommonV10.RequestType Request,
                String RegionalRequestIndicator,
                String MaximumCandidateListSize,
                wwwUpsComXmlschemaXoltwsXavV10.AddressKeyFormatType AddressKeyFormat)
        {
            wwwUpsComXmlschemaXoltwsXavV10.XAVRequest_element request_x = new wwwUpsComXmlschemaXoltwsXavV10.XAVRequest_element();
            wwwUpsComXmlschemaXoltwsXavV10.XAVResponse_element response_x;
            // ... WSDL2Apex generated code removed for brevity ...
            return response_x;
        }
    }
}

Then create the following inner class in your test and repeating lines 11 and 12.

@IsTest
private with sharing class wwwUpsComWsdlXoltwsXavV10Test
{
	private class WebServiceMockImpl implements WebServiceMock
	{
		public void doInvoke(
			Object stub, Object request, Map<String, Object> response,
			String endpoint, String soapAction, String requestName,
			String responseNS, String responseName, String responseType)
		{
			if(request instanceof wwwUpsComXmlschemaXoltwsXavV10.XAVRequest_element)
				response.put('response_x', new wwwUpsComXmlschemaXoltwsXavV10.XAVResponse_element());
			return;
		}
	}
}

Create a test method to cover the generated methods, for each of the methods in generated code repeat line 6 for each. Note that you don’t need to worry about the values being provided to the methods, as the Web Service mock does nothing with them at all. Note that the test context still limits the number of callouts to 10 per test method, so you may need to split the method calls across two test methods.

@IsTest
private with sharing class wwwUpsComWsdlXoltwsXavV10Test
{
	private static testMethod void coverMethods()
	{
		new wwwUpsComWsdlXoltwsXavV10.XAVPort().ProcessXAV(null, null, null, null);
	}
}

Summary. If you want to see a full example of this type of test check out this test class based on the Salesforce Metadata API Web Service. This approach may not be for everyone, certainly if you are already covering a large portion of the generated code or prefer to just delete / comment out the code you don’t need it. However if your providing some kind of connector library or you just want to retain the ability to upgrade the Web Service more easily, or your just determined to keep your 100% code coverage, this might help!